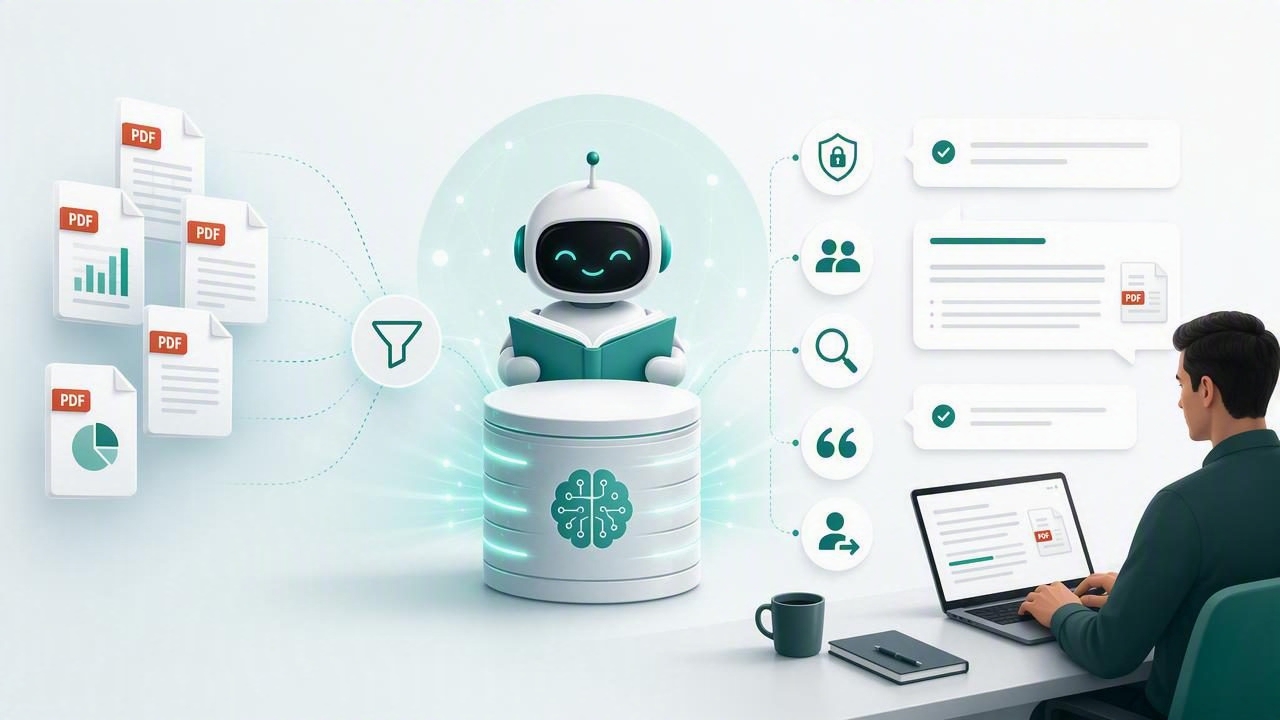
An AI agent knowledge base for client PDFs helps agencies turn scattered documents into useful, conversational answers. Instead of asking team members to manually search brochures, policy documents, product catalogs, onboarding files, contracts, or FAQs, an AI agent can retrieve relevant passages and respond quickly through channels such as WhatsApp.
For agencies managing multiple client accounts, this is more than a convenience feature. A well-designed knowledge base can improve lead qualification, reduce repetitive support work, create more consistent answers, and make client deployments easier to repeat. However, simply uploading PDFs to an AI tool is not enough. To deliver reliable results, agencies need careful document preparation, secure tenant separation, retrieval rules, answer guardrails, and a clear human handoff process.
This guide explains how to plan, build, test, and maintain an AI agent knowledge base that uses client PDFs responsibly.
What Is an AI Agent Knowledge Base for Client PDFs?
An AI agent knowledge base is a searchable collection of business information that an agent can use while answering a user. When the source materials are PDFs, the workflow generally includes extracting text, splitting it into meaningful sections, indexing those sections, retrieving the most relevant content for a question, and using that context to generate an answer.
This approach is often called retrieval-augmented generation, or RAG. Rather than relying only on a model’s general training, the agent grounds its response in current client-specific material.
For example, a prospective customer may ask a WhatsApp agent:
“Does your premium maintenance plan include emergency weekend callouts?”
The agent should search the client’s current service-plan PDF, locate the relevant section, and answer from that source. If the PDF does not clearly state the policy, the agent should avoid guessing and offer to connect the person with a human team member.
Why Agencies Need a Structured PDF Knowledge Strategy
PDFs are common because they are easy for clients to create and distribute. They are also difficult for AI systems when they contain scanned pages, complex tables, outdated terms, duplicated content, or unclear formatting. An agency that treats every uploaded PDF as equally reliable will eventually produce weak answers.
A structured approach provides several operational benefits:
- Faster deployments: Agencies can use a repeatable intake process for each new account.
- More accurate answers: Agents retrieve content from approved, relevant sources.
- Safer multi-client operations: One client’s documents and conversations remain separate from another’s.
- Clearer governance: Account owners can identify which documents are active, outdated, or restricted.
- Better client reporting: Teams can see which questions the knowledge base answers well and where gaps remain.
The objective is not to make an agent answer every question. The objective is to help it answer supported questions accurately, recognize uncertainty, and escalate when necessary.
Prepare Client PDFs Before Uploading Them
Knowledge quality starts before ingestion. Ask clients for the latest approved versions of documents and clarify who has authority to confirm changes. A polished-looking PDF can still contain expired prices, old legal language, or instructions that no longer apply.
Create a document intake checklist
- Document name, owner, and business purpose
- Version number or last-reviewed date
- Client workspace or tenant assignment
- Audience, such as prospects, existing customers, or internal staff
- Permission level and whether the content can be shown externally
- Expiration date or scheduled review date
Scan-based PDFs should go through optical character recognition before indexing. If text cannot be selected or searched in the original file, the extraction process may be unreliable. Tables, price grids, and technical specifications deserve extra review because they can lose structure during extraction.
It is also wise to separate sensitive documents from public-facing material. A sales brochure may be appropriate for a lead-facing WhatsApp agent, while internal margin reports, employee procedures, and confidential agreements should never enter the same retrieval collection.
Design Retrieval Around Useful Document Chunks
AI systems do not usually search an entire 80-page PDF as one unit. Instead, the content is divided into smaller passages known as chunks. Each chunk is stored with metadata and converted into a representation that supports semantic search.
Good chunking preserves context. A section explaining cancellation terms should remain connected to the conditions and exclusions that qualify it. Splitting text blindly every few hundred characters can create incomplete answers and misleading citations.
Useful metadata may include:
document: Premium Service Plan
client_workspace: northstar-services
content_type: customer-facing
version: 4.2
reviewed_on: 2026-02-10
section: Emergency Callout Coverage
access_level: external-agent
Metadata lets the retrieval system filter content before it searches. For example, a customer-facing agent can search only documents marked external-agent, while an internal support assistant may have access to a wider collection.
Use retrieval settings that match the question
Most systems return a small number of relevant chunks for each query. Returning too little context can omit important exceptions. Returning too much can distract the model with unrelated text. Start with a limited set of strong matches, review real conversations, and adjust based on outcomes.
Queries about policies, fees, coverage, legal terms, or product specifications should usually have stricter relevance thresholds than casual questions. If no source passes the threshold, the agent should say that it cannot confirm the answer from the available information.
Keep Client Knowledge Bases Strictly Isolated
Multi-client agency operations require more than separate folder names. Each client needs a logically isolated knowledge base, conversation history, user role structure, and access policy. A retrieval request for one account must never search another account’s PDFs.
At a minimum, enforce tenant filtering at the database or retrieval layer rather than depending only on prompts. Prompts can guide model behavior, but they should not be the only control protecting client data.
| Control | Purpose | Agency Benefit |
|---|---|---|
| Tenant IDs | Filter documents and conversations by client | Prevents cross-client retrieval |
| Role-based permissions | Limit who can upload, edit, or view sources | Supports accountable operations |
| Document status labels | Mark files as active, archived, or restricted | Reduces outdated answers |
| Audit logs | Record uploads, changes, and access events | Simplifies reviews and troubleshooting |
| Retention rules | Delete data when a contract or purpose ends | Improves privacy management |
These controls are especially important when agencies provide white-label AI agent services. Clients expect their data, brand voice, and customer conversations to remain separate even when the agency team manages the underlying platform.
Write Agent Instructions That Prevent Unsupported Answers
Retrieval quality and agent instructions work together. Even excellent PDFs cannot help if the agent is told to answer confidently at all costs. The instruction set should explain what the agent can do, what sources it may use, and how it should react when information is incomplete.
A practical policy may include the following rules:
- Use retrieved client knowledge before answering factual questions.
- Do not invent prices, availability, timelines, policies, or guarantees.
- State when information is unavailable or ambiguous.
- Ask one concise clarifying question when the user’s request is unclear.
- Escalate high-risk, sensitive, or unresolved conversations to a human.
- Share source titles or references when the channel and client workflow support it.
For a WhatsApp AI agent, concise answers are usually best. The agent can give the key answer first, add a short qualification, and offer the next step. Long copied passages from PDFs can overwhelm mobile users and make the conversation feel automated.
Build Human Handoff Into the Knowledge Workflow
Human handoff is not a failure of the AI agent. It is a core part of a trustworthy service design. Some questions require judgment, account access, negotiation, legal review, or real-time operational information that should not be resolved from a PDF.
Define clear escalation triggers, such as:
- The knowledge base does not contain a sufficiently relevant answer.
- The user disputes the agent’s answer or asks for an exception.
- The request concerns payments, cancellations, complaints, safety, or legal commitments.
- A qualified lead asks for a quote, appointment, or tailored proposal.
- The agent detects repeated confusion after one clarification attempt.
When a handoff occurs, pass useful context to the human team: the conversation summary, user intent, relevant retrieved documents, and any unanswered question. This prevents the customer from repeating themselves and turns the agent into a productive first-response layer rather than a dead end.
Test Your Knowledge Base Before Going Live
Do not evaluate an AI agent knowledge base for client PDFs using only a few obvious questions. Build a test set from real customer inquiries, sales calls, email tickets, and edge cases. Include questions that should be answered, questions that should trigger clarification, and questions that should result in handoff.
Track more than answer quality. Review whether the agent used the correct client source, respected permissions, avoided unsupported claims, and followed the expected tone.
Useful evaluation metrics
- Grounded answer rate: Percentage of answers supported by retrieved documents.
- Retrieval precision: How often the top results contain the correct source material.
- Handoff accuracy: Whether sensitive or uncertain requests reach a human promptly.
- Knowledge gap rate: Frequency of valid questions with no approved source.
- Resolution rate: Percentage of conversations resolved without human intervention.
Review low-confidence interactions weekly during the early stages of deployment. These conversations reveal missing documents, unclear client policies, weak chunking, and instructions that need refinement.
Maintain the Knowledge Base as a Living System
A knowledge base is not a one-time upload. Client information changes constantly: product lines evolve, prices change, promotions expire, and operational policies are updated. Without maintenance, even a technically strong retrieval system becomes less useful over time.
Set a recurring review cycle with each client. Confirm active documents, archive outdated files, and identify frequently asked questions that deserve dedicated source content. In many cases, a concise, approved FAQ is easier for an agent to retrieve accurately than a dense 50-page manual.
Agencies should also distinguish between a document update and a policy change. Updating a PDF may refresh the agent’s source material, but a major policy change may require updated agent instructions, revised escalation rules, and fresh test cases.
Final Takeaway
A reliable AI agent knowledge base for client PDFs combines clean source documents, thoughtful chunking, strict client isolation, permission controls, grounded response rules, and human handoff. Agencies that treat knowledge management as an operational discipline can create more dependable AI experiences across multiple client accounts.
Whether using a managed service or self-hosted AI software, choose an approach that supports client-level separation, document governance, and transparent agent behavior. Platforms such as OpenLivery can fit this model when agencies need branded, multi-client AI agent operations with controlled knowledge and conversations.