When an agency launches an AI agent for a new client, the first version often depends on a mix of PDFs, website pages, spreadsheets, and messages from busy subject-matter experts. The agent may answer correctly at launch, but the underlying information quickly becomes difficult to review, update, and reuse. Without a consistent process, each new client becomes a custom research project—and every change creates another opportunity for errors.
A well-designed client knowledge base for repeatable agency delivery solves more than a retrieval problem. It gives teams a reliable way to collect, organize, approve, test, and maintain information for each client’s AI agents. The goal is not to make every client’s knowledge identical. It is to make the method consistent while preserving each client’s unique facts, policies, voice, and permissions.
This guide explains how agencies can build that operating system, from discovery through ongoing maintenance, for WhatsApp AI agents and other client-facing assistants.
What a client knowledge base should do
A client knowledge base is the approved information an AI agent can use to answer questions or guide a conversation. It might contain product details, service areas, pricing rules, return policies, appointment instructions, troubleshooting steps, or escalation contacts. It can include structured records as well as documents, but it should never be treated as an unfiltered folder of everything the client has ever shared.
For agency delivery, the knowledge base needs to support four outcomes:
- Accuracy: agents can find current, approved answers rather than guessing from outdated material.
- Repeatability: the agency follows the same intake, review, and launch process for every account.
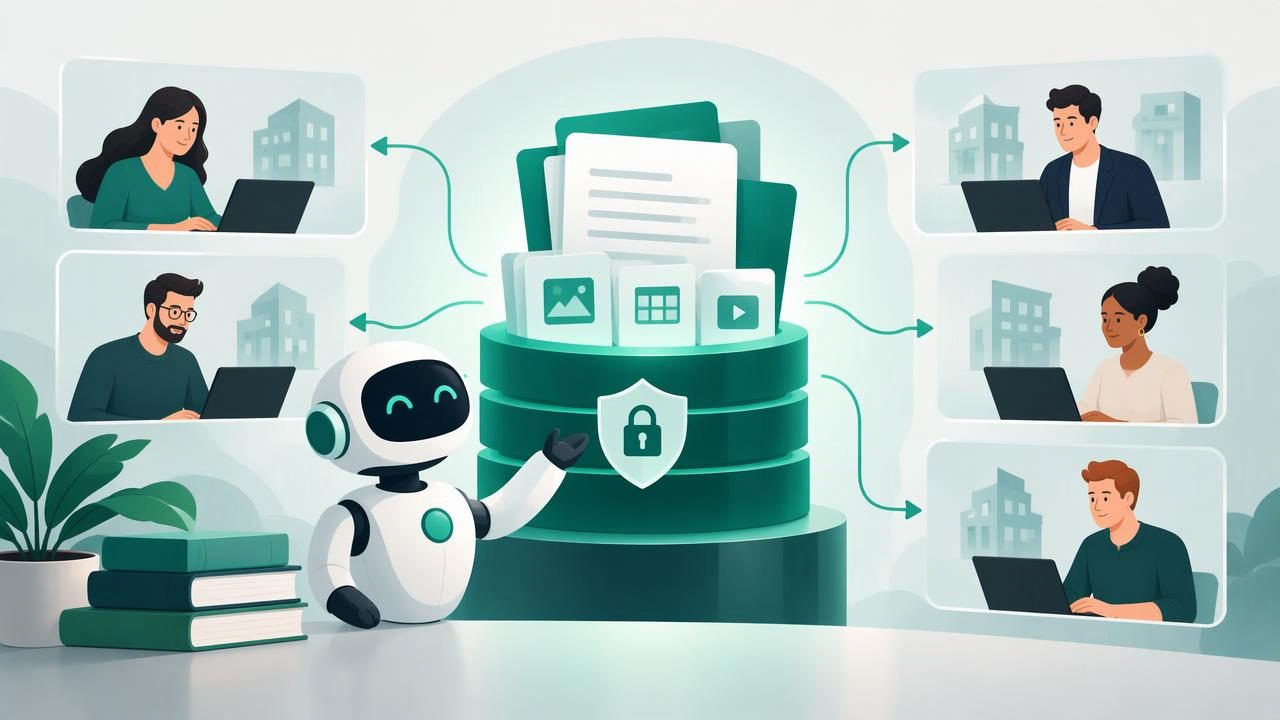
- Isolation: each client’s knowledge and conversations stay separate from other clients’ data.
- Maintainability: teams can identify who owns a fact, when it was checked, and what needs updating.
These outcomes matter whether an agency uses a managed AI agent cloud or self-hosted AI software. The platform handles storage and retrieval; the agency’s process determines whether the information is trustworthy.
Start with a repeatable discovery process
Do not begin by asking a client to “send over everything.” That request tends to produce duplicates, old files, and material that was never meant for customers. Instead, run a structured discovery session around the questions the agent is expected to handle.
Ask the client to identify the agent’s audience, channels, business goals, and boundaries. For example, should a WhatsApp AI agent answer product questions, qualify leads, book appointments, or all three? Which requests must go directly to a person? What information is sensitive, and what should the agent never promise?
Then map the most common customer questions to authoritative sources. A useful intake table can look like this:
| Information area | Source to request | Owner | Review trigger |
|---|---|---|---|
| Products and services | Approved catalog or service page | Product lead | New offering or price change |
| Policies | Current policy document | Operations or legal | Policy revision |
| Lead qualification | Sales criteria and sample questions | Sales manager | Campaign or qualification update |
| Escalations | Contact roles and handoff rules | Support lead | Staffing or coverage change |
Record gaps as gaps. If nobody can confirm a refund rule, the right next step is to ask the client—not to let the agent infer an answer from an old email.
Use a consistent structure without flattening client differences
A reusable framework makes agency work faster, but a rigid template can hide important differences. Create a standard set of knowledge categories, then allow client-specific fields where necessary. Common categories include company overview, products and services, eligibility, pricing, policies, procedures, FAQs, terminology, and escalation instructions.
For each item, capture more than the answer itself. Include its source, owner, approval status, effective date, review date, and any conditions that limit its use. A short answer such as “Delivery is available” is not enough if availability depends on location, order size, or business hours.
For high-impact information, prefer structured entries over a long document. For example, a service-area record might include the locations served, exceptions, and the date the list was verified. Narrative documents still have a role, especially for detailed procedures, but clear structure makes critical rules easier to inspect and test.
Make client isolation a design requirement
In multi-client agency operations, isolation is not merely a matter of neat folders. Each client needs its own knowledge, agent configuration, and conversation history. A retrieval system should only search content authorized for the active client and agent. A shared workspace can simplify administration, but shared infrastructure must not mean shared client data.
Define permissions before onboarding begins. Decide who can upload files, approve answers, edit agent instructions, view conversations, and manage integrations. Apply the principle of least privilege: give each user only the access their role requires. Keep agency-wide templates separate from client-specific material, and never use one client’s documents as another client’s source.
These safeguards matter when using OpenAI-compatible models as well as proprietary models. Model choice does not replace access controls, retention policies, or careful handling of personal information. Agencies should document what data is sent to providers, how long logs are retained, and who can export or delete records.
Prepare source material before adding it to an agent
Knowledge quality often suffers before retrieval even begins. PDFs may contain scanned pages, conflicting versions, or tables that extract poorly. Web pages can include navigation and promotional copy that distract from the answer. Before ingestion, check that each source is readable, current, relevant, and approved for customer-facing use.
- Inventory: list every candidate source and its owner.
- Verify: confirm the current version and remove duplicates or superseded files.
- Normalize: use consistent headings, labels, and terminology where practical.
- Scope: separate customer-safe facts from internal notes, credentials, and sensitive records.
- Approve: obtain sign-off from the person responsible for the information.
Do not assume that uploading more material improves the agent. A smaller, approved knowledge base is usually easier to evaluate than a large archive with unclear authority.
Connect knowledge to agent behavior and human handoff
Knowledge and instructions work together. The knowledge base provides facts; the agent’s instructions define how to use them. Specify that the agent should answer from approved sources, ask a clarifying question when required details are missing, and say when it cannot verify an answer. Explicitly prohibit invented prices, guarantees, eligibility decisions, and policy exceptions.
Set handoff rules for situations where automation should stop. Examples include complaints, legal or medical questions, uncertain policy cases, sensitive account changes, and requests to speak with a person. A useful handoff should carry context: the customer’s question, relevant answers already given, and the reason for escalation. That reduces repetition and helps a human continue the conversation smoothly.
For WhatsApp AI agents, test the experience in the shape customers actually use it: short messages, typos, voice-note transcripts, multiple questions in one message, and follow-up replies that rely on earlier context.
Test answers before launch—and after updates
Build a test set from real customer questions, anonymized where needed, and include questions the agent should not answer. For each test, define the expected answer, acceptable variations, relevant source, and whether a handoff is required. Ask client reviewers to check high-risk answers rather than relying solely on the agency team.
Measure more than whether an answer sounds fluent. Review factual correctness, source relevance, unsupported claims, appropriate refusal, and successful escalation. Keep a record of failures and their causes: missing information, conflicting sources, retrieval issues, or unclear agent instructions. Each cause needs a different fix.
After a knowledge update, rerun related tests. A new pricing document might fix one answer while unintentionally conflicting with an FAQ. Version history and a simple change log help the team understand what changed, who approved it, and which tests were repeated.
Turn maintenance into a clear client service
Knowledge bases decay as products, staff, schedules, and policies change. Assign an owner at both the agency and client levels. Set review dates based on risk: frequently changing prices may need monthly checks, while a stable company description may only need an occasional review. Also define event-based triggers, such as a product launch or policy change.
Give clients a simple update path. They should know where to submit a change, what details to include, and who approves it. The agency can then verify the source, update the relevant entry, run regression tests, and record the release. This makes ongoing care visible and can support recurring agency revenue through monitoring, content maintenance, testing, and optimization—not just initial implementation.
A practical launch checklist
- Define the agent’s audience, tasks, limits, and escalation conditions.
- Identify authoritative sources and accountable owners.
- Separate client data and assign role-based permissions.
- Remove stale, duplicate, irrelevant, or sensitive content.
- Record approval, source, effective date, and review schedule.
- Test expected questions, edge cases, and handoff behavior.
- Document update, rollback, and client approval procedures.
Build a system, not a pile of documents
A repeatable client knowledge base is an operating process: discover, structure, approve, isolate, test, and maintain. Standardizing those steps helps agencies launch more consistently without forcing every client into the same answers or brand experience. It also gives clients a clearer role in keeping their AI agents dependable.
Choose tools that make client boundaries, permissions, knowledge management, and human handoff visible to the people responsible for delivery. Platforms such as OpenLivery are one option agencies may evaluate when they need to manage branded agents and separate client workspaces; the right choice depends on each agency’s technical, security, and operational requirements.