For an agency, an AI agent platform is more than a way to publish a chatbot. It becomes part of the service delivered to every client. The model behind an agent affects response quality, speed, cost, privacy, and the kinds of tasks the agent can handle. That is why agencies evaluating how to get flexible model choice with a white label AI agent platform should look beyond a long list of model names.
True flexibility means being able to connect suitable models, assign them to the right client or task, and change them without rebuilding the entire service. It also means keeping branding, permissions, knowledge, conversation history, and human handoff under control. This guide explains what to look for and how to evaluate model choice in practical terms.
What flexible model choice actually means
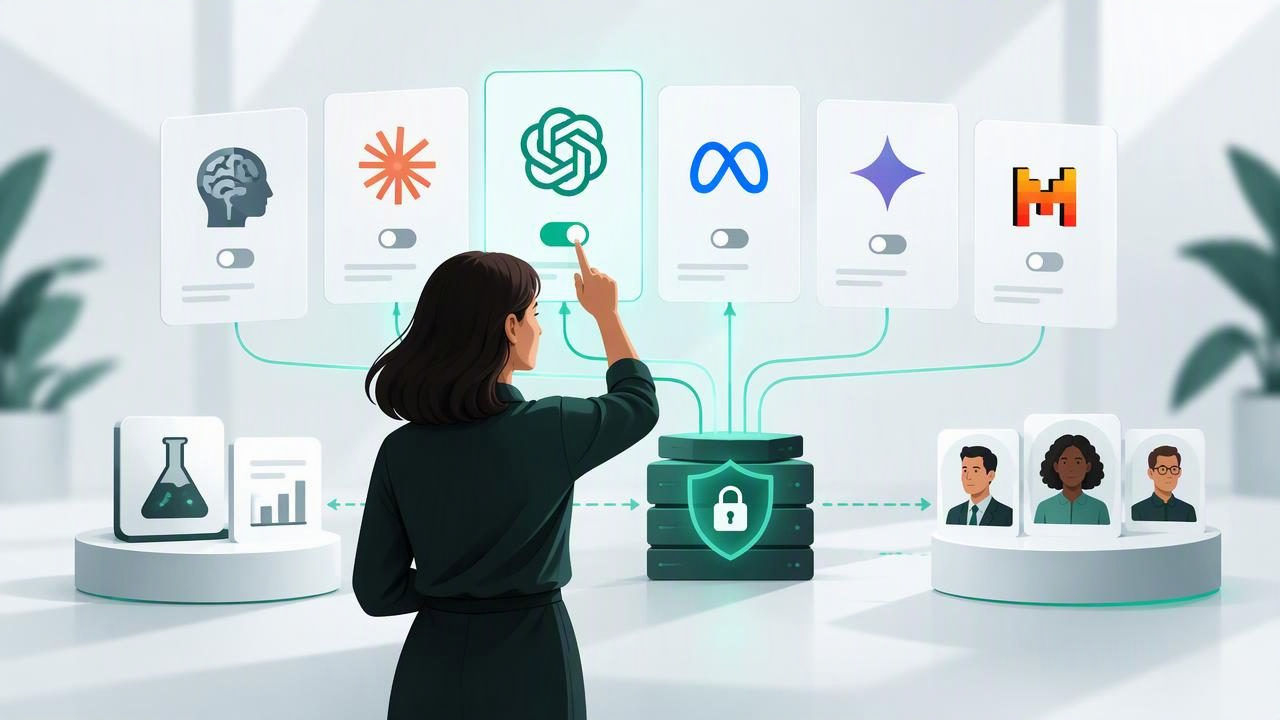
A platform may advertise support for multiple models, but that alone does not guarantee useful choice. Check whether you can select a model per agent, client, or workflow; configure credentials securely; and switch providers without losing the agent’s instructions or client-specific setup. A provider-neutral integration, such as support for OpenAI-compatible APIs, can make it easier to connect different hosted services and compatible endpoints.
Flexibility also includes operational control. You should be able to test a model before rolling it out, monitor how it performs, and decide what happens if a provider is unavailable. The goal is not to use every available model. It is to match the model to the job while retaining the freedom to adjust as client needs and provider offerings change.
Why agencies need more than one model
Different clients have different requirements. A local service business may need quick answers to common questions, while a professional firm may prioritize careful responses grounded in approved documents. Another client may need multilingual support or a lower-cost option for handling high message volumes. One model is unlikely to be the best choice for every use case, workload, and budget.
Multiple options can also reduce dependency on a single provider. If pricing changes, availability drops, or a model’s performance shifts, an agency with a portable setup has more room to respond. That does not mean switching providers should happen casually: changes can affect tone, accuracy, latency, and output format. It means you can make a deliberate choice instead of being locked into a single path.
Evaluate the platform, not just the model menu
Use the following criteria to judge whether model choice is meaningful for agency operations:
- Connection options: Can the platform connect to more than one provider, including compatible endpoints where appropriate?
- Configuration scope: Can models be assigned independently to different clients, agents, or tasks?
- Credential handling: Are API keys protected and restricted to authorized administrators?
- Portability: Can you change the model without recreating prompts, knowledge sources, or workflows?
- Observability: Can your team review errors, usage, latency, and outcomes at an appropriate level?
- Fallback behavior: Can you define what the agent should do when a model or provider is unavailable?
- Human oversight: Can conversations be escalated when the agent lacks confidence or the request needs a person?
Ask for a demonstration of these controls using separate sample clients. A platform may support many models technically while still making it difficult to manage them safely across a real agency portfolio.
Match models to client tasks
Start by describing what the agent must do, rather than choosing a model because it is popular. Identify the expected message volume, languages, response time, risk level, and knowledge sources. Then decide which tasks require stronger reasoning and which can be handled by a smaller or faster option.
| Task profile | What to prioritize | What to test |
|---|---|---|
| Frequently asked questions | Speed, consistency, and cost | Accuracy against approved answers and handling of unknowns |
| Document-based support | Grounded responses and clear limitations | Whether answers reflect the right passages in client files |
| Lead qualification | Reliable question flow and useful summaries | Whether required details are collected without repetitive questions |
| Complex or sensitive requests | Careful reasoning and escalation controls | Whether the agent recognizes uncertainty and hands off appropriately |
This is a starting point, not a universal ranking. Model performance depends on the prompt, retrieval setup, language, and task. A well-designed agent using a less expensive model may outperform a more capable model that has unclear instructions or poor client knowledge.
Separate model choice from client knowledge
Client knowledge should be managed as a distinct part of the agent configuration. A model generates responses; the knowledge base supplies client-specific information such as policies, service details, and approved documents. Keeping these concerns separate makes it easier to test a new model without mixing one client’s data into another client’s setup.
For each client, organize source material, remove outdated versions, and define what the agent may answer from those sources. Test questions that are answered in the documents and questions that are not. The agent should communicate uncertainty instead of inventing a policy. This is particularly important for WhatsApp AI agents, where short, conversational replies can sound confident even when the underlying information is incomplete.
Design a safe model-switching process
Changing a model is a production change, even if the agent’s visible behavior seems similar. Use a repeatable process rather than editing a live configuration and hoping for the best:
- Record the current setup: Save the model identifier, instructions, relevant settings, knowledge sources, and escalation rules.
- Build a representative test set: Include common questions, edge cases, unsupported requests, multiple languages, and examples that should trigger a human handoff.
- Run a side-by-side evaluation: Compare the existing and candidate models using the same prompts and knowledge.
- Review more than correctness: Check tone, completeness, response time, consistency, and cost as well as factual accuracy.
- Roll out gradually: Test with an internal group or limited traffic before changing every client agent.
- Keep a rollback path: Know how to restore the previous configuration if quality or availability declines.
Human review is valuable during testing. A numerical score can help compare responses, but it may miss a subtle issue such as a model promising a service the client does not offer or failing to recognize an upset customer.
Build a practical evaluation scorecard
Score each candidate against criteria your agency and client care about. For example, rate answer grounding, instruction following, unsupported-answer behavior, tone, latency, and estimated cost. Define what counts as an acceptable result before testing so a low price does not quietly outweigh a serious quality problem.
Use realistic WhatsApp conversations rather than isolated, perfectly phrased questions. Messages may contain typos, missing context, voice-to-text errors, or several requests at once. Test what happens when a person changes topics, asks for something outside the client’s services, or requests a human. Keep test data appropriate for the environment and avoid using real sensitive conversations without authorization.
Protect client boundaries and credentials
Flexible model choice must not weaken agency security. Each client should have isolated agents, knowledge, and conversations, with permissions that reflect staff roles. An account manager who supports one client may not need access to another client’s credentials or conversation history. Review how the platform separates tenants and how it logs administrative changes.
Store provider credentials using the platform’s approved secret-management process. Limit who can add or replace keys, avoid placing secrets in prompts or shared documents, and rotate credentials when staff access changes or a key may have been exposed. Confirm what information is sent to each model provider and assess whether that use aligns with the agency’s client agreements and privacy requirements.
Plan for cost, latency, and provider outages
Model flexibility can help control costs, but compare the full workflow rather than a provider’s headline price. Usage may include repeated model calls, retrieved context, retries, and long conversation histories. Track consumption by client where possible so that an agency can price services responsibly and identify unexpected increases.
Latency matters too. A technically capable model that responds too slowly may create a poor customer experience in a messaging channel. Set sensible limits, test during realistic traffic, and define a fallback response for outages. In some situations, the safest fallback is not another model: it may be a brief message explaining that a person will follow up.
Questions to ask before choosing a white-label platform
- Can each client have a separate model configuration and independent agent settings?
- Can we connect OpenAI-compatible models or other supported providers without rebuilding each agent?
- How are API credentials stored, scoped, and audited?
- What usage, error, and latency information can agency administrators review?
- Can an agent pause or hand off a conversation to a human when needed?
- Can we export or retain our configurations if we change hosting or providers?
- Does the platform offer a managed cloud option, self-hosting, or both?
The answers should be specific. Terms such as “model agnostic” or “enterprise-ready” are not substitutes for showing how a client-level change works, who can make it, and how it is recorded.
Choose flexibility that your team can operate
The strongest model strategy is not necessarily the one with the most integrations. It is the one your team can govern consistently across clients. Standardize how you test, document, approve, and monitor model changes. At the same time, allow justified exceptions when a client’s language, risk profile, budget, or workflow calls for a different configuration.
Review model performance periodically, especially after changes to provider behavior, client documents, or conversation flows. Treat feedback and handoff patterns as signals: repeated escalations may point to missing knowledge, unclear instructions, or a task that should not be automated. Keep humans responsible for decisions that require judgment, authorization, or personal care.
When comparing platforms, agencies can assess both managed services and self-hosted AI software. A managed cloud can reduce infrastructure work; self-hosting may offer more deployment control but requires operational expertise. Open-source options can make the underlying stack more inspectable, yet still require careful maintenance and security practices. OpenLivery is one example of an agency-focused platform that provides a managed cloud and a self-hostable option.
Ultimately, flexible model choice is valuable when it supports better client outcomes without making operations unpredictable. Choose a platform that lets you connect appropriate models, keep each client’s data and configuration separate, evaluate changes before rollout, and involve people when the agent reaches its limits. That combination gives an agency room to adapt while preserving trust in every branded experience.