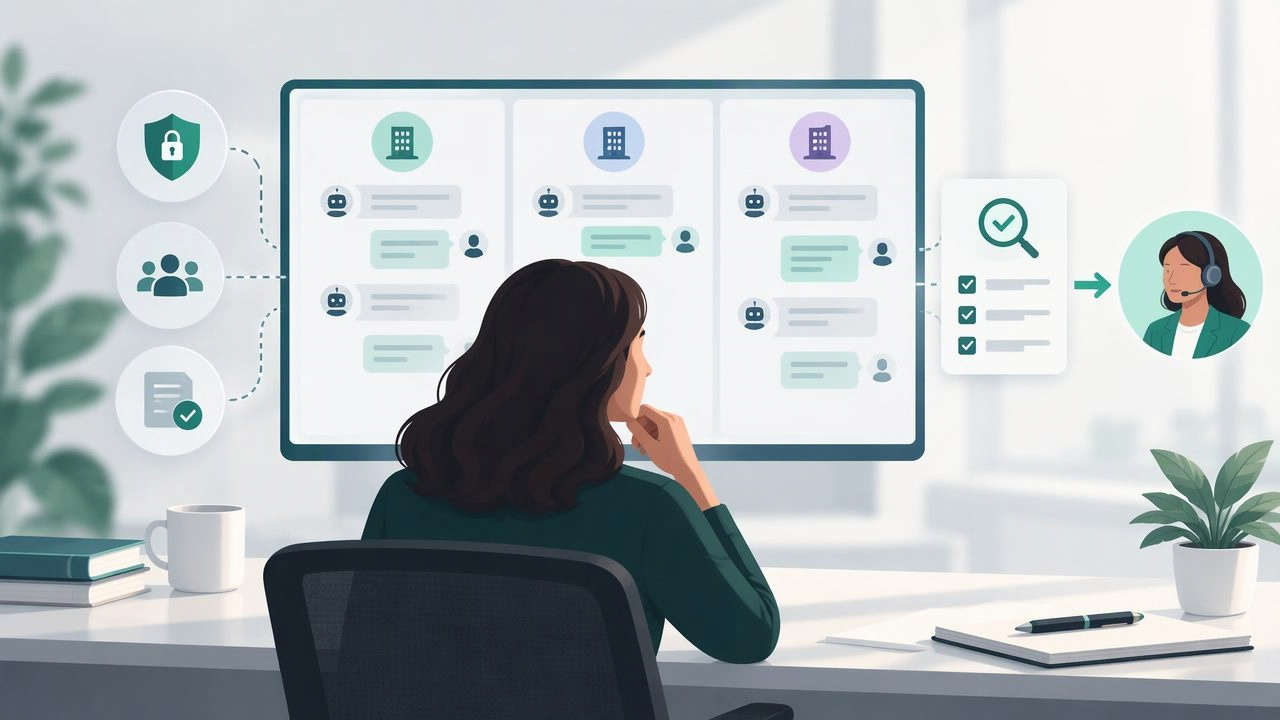
When an agency manages WhatsApp AI agents for several clients, conversation review is essential—but it can quickly become difficult to do well. Teams need to check whether agents give accurate answers, qualify leads consistently, and hand sensitive or complex questions to a person. At the same time, they must keep each client’s conversations and knowledge private.
A strong review process makes oversight repeatable. Instead of browsing chats at random, agency teams define who can access each account, what to inspect, how to record findings, and when to escalate an issue. This guide explains how to review conversations across client accounts without blurring boundaries or creating unnecessary work.
Why conversation reviews matter
AI agents can respond quickly, but speed does not guarantee quality. A response may be factually wrong, too vague, outside the client’s policies, or based on an outdated document. Lead qualification can also fail if the agent asks the wrong follow-up question or misses a clear buying signal.
Reviewing real conversations helps an agency spot these problems early. It also shows whether the agent’s instructions and client knowledge base are working as intended. With a consistent process, reviews can help teams:
- Find incorrect, incomplete, or unsupported answers.
- Check whether leads are qualified and routed correctly.
- Confirm that human handoff happens when it should.
- Identify repeated questions that may point to gaps in client documents.
- Share useful performance insights with each client.
The aim is not to read every message. It is to sample conversations systematically, investigate exceptions, and turn findings into clear improvements.
Start with account boundaries and permissions
Before reviewing any chat, establish which team members may see which client accounts. In a multi-client agency operation, one broad administrator login can expose conversations or documents to people who do not need them. Separate access by client and role wherever the platform allows it.
A practical permission model might include:
- Agency administrators: Manage the platform, assign access, and investigate cross-account operational issues.
- Client account managers: Review conversations and settings for the accounts they own.
- Quality reviewers: Inspect assigned conversations, ideally without permission to change agent settings.
- Client users: View their own conversations or reports, but not other clients’ data.
Use named accounts rather than shared credentials, remove access when a person changes roles, and review permissions on a schedule. If your platform supports audit logs, check them during routine security reviews. These controls reduce accidental exposure and make it easier to understand who accessed an account.
A repeatable review workflow in seven steps
- Choose a review purpose. Decide whether the session is checking factual accuracy, lead qualification, tone, policy compliance, handoff, or a particular release. A defined purpose keeps reviewers focused.
- Select a useful sample. Include a mix of ordinary interactions and higher-risk cases. For example, sample recent conversations from each client, then add chats with a low confidence signal, a human handoff, a complaint, or an unanswered question. Follow a consistent sampling rule rather than choosing only memorable chats.
- Confirm the client context. Check the account, agent version, relevant instructions, and knowledge sources before judging a reply. A response may look incorrect if the reviewer is using a different policy or an old document.
- Read the full interaction. Review the user’s question, the agent’s response, and any follow-up messages. A short answer can be appropriate in context, while a seemingly helpful answer may have missed an earlier constraint.
- Score against a rubric. Record specific evidence for each rating. Avoid vague feedback such as “bad answer”; identify what was wrong and what a good response should have done.
- Assign an action and owner. Decide whether the issue needs an instruction change, a knowledge-base update, a routing adjustment, human follow-up, or no change. Set a due date for important fixes.
- Recheck after changes. Review new conversations to confirm that the fix worked and did not introduce a different problem.
Use a shared scorecard, not subjective impressions
A short scorecard helps different reviewers reach similar conclusions. Keep criteria specific to the agent’s job, and allow a reviewer to mark an item as not applicable. One example is below:
| Review area | Question to ask | Example rating |
|---|---|---|
| Accuracy | Is the answer supported by the client’s approved information? | Pass, partial, fail |
| Relevance | Does it respond to the user’s actual question? | Pass, partial, fail |
| Qualification | Does it ask useful follow-up questions and capture intent? | Pass, partial, fail |
| Policy and tone | Does it follow client requirements and sound appropriate? | Pass, partial, fail |
| Handoff | Was a person involved when the situation required one? | Yes, no, not applicable |
Include a notes field for evidence, plus a severity label such as low, moderate, or urgent. A wrong opening time may need a document correction; a sensitive request that received an unsafe answer may require immediate escalation. Severity helps teams prioritize without treating every imperfection as a crisis.
Protect client privacy during reviews
Conversation review should follow the same data boundaries as agent operation. Do not copy client messages into a shared spreadsheet, general-purpose chat, or personal notes unless the agency has an approved reason and suitable safeguards. Store review outcomes in the relevant client workspace, and include only the minimum conversation detail needed to explain a finding.
Consider whether reviewers need access to the full conversation or whether a limited view is enough. Establish retention rules for review notes and exports, and follow the client’s instructions and applicable privacy requirements. When using an external model to analyze transcripts, check what data is sent, how it is handled, and whether that use is authorized. OpenAI-compatible models may share an interface format, but their data practices and deployment arrangements can differ.
For self-hosted AI software, agencies should also secure infrastructure, databases, backups, and administrator access. A self-hosted deployment gives an organization more control over its environment, but it also makes security configuration and maintenance the operator’s responsibility.
Make human handoff part of the review
Human handoff is not simply a button or routing rule. Reviewers should verify that the agent recognizes situations that need a person, provides a clear transition, and passes along enough context for the human to respond. Check whether the user was told what would happen next and whether the conversation reached the right team.
Useful handoff triggers can include a direct request to speak with someone, a complaint, an unusual billing or account issue, low confidence, or a question that the approved knowledge base cannot answer. Triggers should reflect each client’s workflow; a rule suitable for a clinic may not fit a retail business. When a handoff fails, assign an owner to investigate both the agent behavior and the routing destination.
Turn review findings into improvements
A review is valuable only if its findings lead to action. Group recurring issues by likely cause: missing client information, unclear instructions, an overbroad answer, a tool or integration problem, or a handoff rule that needs adjustment. Fix the underlying cause when possible instead of adding a one-off instruction for every conversation.
Keep a simple issue log with the client, date, category, severity, owner, action, and follow-up status. Share trends with the client in a way that respects their access boundaries. For example, report that several users asked about a service area not covered in the current documents, rather than exposing unrelated chats to people who do not need them.
Measure coverage and quality over time
Review counts alone do not show whether oversight is effective. Track a small set of operational measures, such as the share of accounts reviewed during the period, the percentage of sampled chats that meet the scorecard, recurring failure categories, handoff completion, and time to resolve urgent findings. Compare trends within the same client account, since agents may have different goals and risk levels.
Use metrics as signals for investigation, not as proof that an agent is safe or successful. A high pass rate from a tiny or unrepresentative sample can be misleading. Increase sampling after a major instruction change, new knowledge-base upload, model update, or spike in complaints. Reduce it only when the risk and performance evidence support doing so.
Build oversight into everyday agency operations
To review conversations across client accounts reliably, combine clear access controls with a repeatable sampling process, a shared scorecard, documented actions, and follow-up checks. Keep reviews client-specific, minimize unnecessary transcript copies, and make human handoff a measurable part of quality assurance.
These habits help agencies improve AI responses while preserving the boundaries that multi-client work requires. Teams evaluating platforms can compare how each handles account isolation, reviewer permissions, audit history, and human escalation. OpenLivery is one example of an open-source platform designed for agencies managing branded WhatsApp agents across separate client accounts.